
Deep learning is one of the most important technologies behind modern artificial intelligence. It allows computers to recognize images, understand human language, process speech, and identify complex patterns in information. Many familiar digital services use deep learning to improve how they respond to users and perform tasks.
Unlike traditional computer programs that follow fixed instructions, deep learning systems learn patterns from examples. They use artificial neural networks containing multiple layers to process data and make predictions. Through repeated training, these networks adjust their internal parameters to improve their performance on specific tasks.
Understanding how deep learning works becomes easier when its main components are explained in simple terms. You do not need advanced mathematical knowledge to understand the basic process. This guide explores neural networks, training methods, different architectures, real-world applications, and the important limitations of deep learning technology.
What Is Deep Learning?
Deep learning is a specialized branch of machine learning that uses artificial neural networks with multiple processing layers. These networks learn relationships within data and apply those relationships to new information. The technology supports tasks such as image classification, speech recognition, language processing, and numerical prediction.
The word “deep” refers to the number of computational layers involved in processing information. Each layer transforms the outputs received from previous layers into new representations. This layered arrangement helps the network learn increasingly complex features without requiring developers to describe every important pattern manually.
Deep learning is particularly useful when traditional programming rules cannot easily capture the complexity of a problem. For example, recognizing objects in photographs involves differences in lighting, position, shape, and background. Neural networks can learn useful visual patterns by examining relevant examples during training.
How Deep Learning Works Step by Step
Deep learning works by feeding information into a neural network that contains interconnected processing layers. The network performs mathematical calculations on the input and generates an output. That output might be a category label, a numerical prediction, or a sequence of generated text.
During training, the model compares its output against a defined learning objective. A loss function measures how far the output is from the desired result. An optimization algorithm then adjusts the network’s internal parameters to help improve predictions during subsequent training steps.
This cycle repeats across many examples until training reaches a suitable stopping point. As the parameters change, the network can develop representations that capture useful relationships in the data. Its ability to perform well on unfamiliar examples depends on training quality, model design, and proper evaluation.
Understanding Artificial Neural Networks
Artificial neural networks are computational systems loosely inspired by the organization of biological nervous systems. They contain connected processing units known as artificial neurons. These units perform mathematical operations on incoming information and pass their results to other parts of the network.
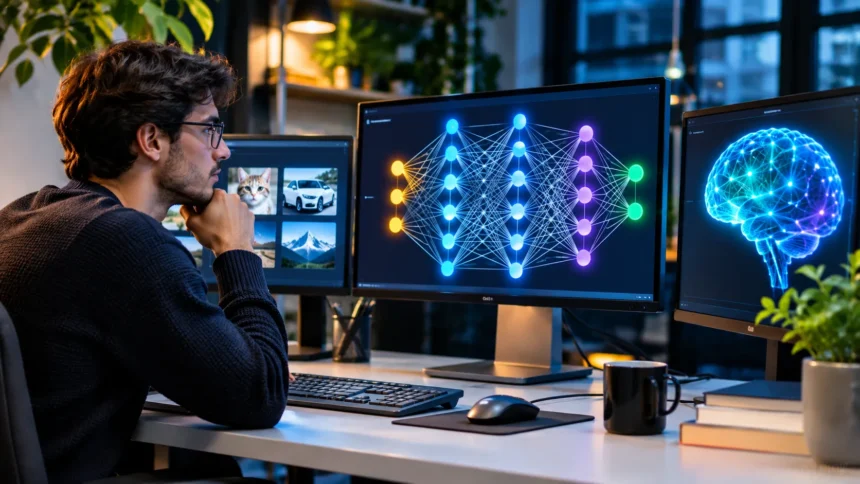
A typical feedforward neural network contains an input layer, one or more hidden layers, and an output layer. Each layer has a different role in processing information. Together, these layers transform raw data into representations that the network can use to produce predictions or classifications.
The connections between artificial neurons contain adjustable numerical values called weights. During training, these weights change according to the optimization process. This ability to adjust internal parameters allows neural networks to learn patterns instead of depending entirely on manually written decision rules.
The Role of Input Layers in Deep Learning
The input layer is the starting point where information enters a neural network. Depending on the application, this information may include image pixels, numerical measurements, audio features, or encoded text. The input representation determines how the network receives and begins processing the data.
For example, an image recognition model may receive numerical values representing the colors or brightness of pixels. A financial forecasting model might receive historical measurements arranged into a suitable sequence. Language systems commonly process text after converting it into numerical representations called tokens or embeddings.
Preparing input data correctly is important because models cannot automatically understand every possible information format. Developers may need to resize images, normalize numerical values, or organize sequences. Suitable preprocessing helps ensure that the network receives consistent information during training and prediction.
How Hidden Layers Process Information
Hidden layers perform much of the transformation involved in deep learning. They receive numerical information from earlier layers and apply learned mathematical operations. Their outputs become inputs for later layers, creating a sequence of increasingly useful representations for the network’s intended task.
In some image recognition networks, earlier layers may respond to simple visual features such as edges or textures. Later layers can combine these features into more complicated representations. The precise patterns learned depend on the model architecture, training data, and optimization process.
Different neural network architectures organize hidden layers in different ways. Some use convolution operations, while others rely on attention mechanisms or recurrent connections. The underlying goal remains similar: transform information into representations that help the model perform its assigned task effectively.
Why Output Layers Are Important
The output layer produces the final result of a forward pass through a neural network. Its structure depends on the problem being solved. For example, a classification model may generate scores for different categories, while a regression model produces numerical predictions.
Consider a system trained to recognize photographs of animals. The output layer might provide values associated with categories such as cats, dogs, and birds. Additional calculations can convert those values into probabilities or other useful scores, depending on the model design.
Output layers must match the learning objective used during training. A model predicting continuous measurements requires different output handling from a system classifying images. Choosing an appropriate structure helps developers connect the network’s calculations to meaningful and measurable results.
What Are Weights and Biases in Deep Learning?
Weights are adjustable numerical parameters that determine how strongly certain signals influence calculations within a neural network. Each connection can contribute differently to the information being processed. During training, changing these weights helps the model represent useful relationships within its data.
Biases are additional learnable values that provide flexibility in how neurons calculate their outputs. They allow certain transformations to shift independently of the incoming weighted values. Together, weights and biases form an important part of the trainable parameters found in many neural network architectures.
At the beginning of training, these parameters are usually initialized according to a chosen strategy. Optimization algorithms gradually update them based on feedback from the loss function. Successful learning depends on coordinated adjustments across many parameters rather than changing individual values manually.
How Activation Functions Help Neural Networks Learn
Activation functions transform the numerical outputs produced by neurons or layers. They introduce nonlinear behavior, which allows networks to represent relationships that simple linear calculations cannot capture. Without suitable nonlinear operations, stacking several ordinary linear layers would provide limited additional modeling power.
Common activation functions include ReLU, sigmoid, and hyperbolic tangent. Each has different mathematical characteristics that may suit particular layers or applications. ReLU and related functions are widely used in many neural network designs because of their practical training properties.
The choice of activation function can influence training behavior and model performance. Some functions may create optimization difficulties under certain conditions. Developers select them based on the architecture, learning objective, and characteristics of the problem rather than using one function everywhere.
How Deep Learning Models Learn From Training Data
Training data provides the examples and patterns that a neural network uses to adjust its parameters. Depending on the learning method, examples may include labels, target values, or information that supports self-supervised objectives. The model processes these examples to improve its ability to perform a defined task.
In supervised image classification, training data might contain photographs labeled with their correct categories. The network predicts a category and compares its output with the provided label. This comparison generates a learning signal that guides adjustments to the network’s weights and biases.
The quality and diversity of training examples directly influence what the model can learn. Incorrect labels, limited coverage, and unrepresentative samples can lead to unreliable predictions. Careful dataset preparation and evaluation are therefore essential parts of building effective deep learning systems.
What Is Forward Propagation in Deep Learning?
Forward propagation is the process of passing information through a neural network to calculate an output. Input data moves through successive computational operations according to the model architecture. Each layer applies its current parameters to transform the information it receives.
For example, an image classification system processes image values through several layers before producing category scores. The calculations use the weights and biases currently stored in the network. Forward propagation itself does not normally update these parameters or determine whether the prediction is correct.
The resulting output can be compared with an expected answer during training. In practical applications, the same general forward computation is also used to make predictions on new data. Understanding this process provides a foundation for learning how neural networks are trained.
Understanding Loss Functions and Prediction Errors
A loss function measures how well a neural network’s output matches its training objective. It converts differences between predictions and desired outcomes into a numerical value. Training algorithms use this value to guide improvements in the model’s internal parameters.
Different tasks require different loss functions. Classification systems commonly use cross-entropy-based objectives, while numerical prediction problems may use mean squared error. Other learning methods define losses that compare representations, reconstruct information, or estimate probabilities without conventional category labels.
A lower training loss does not always mean the model will perform better on unfamiliar information. Networks may learn patterns that are specific to their training examples. Developers therefore monitor validation performance and other evaluation measures instead of focusing only on reducing training loss.
How Backpropagation Works in Neural Networks
Backpropagation is a mathematical method used to calculate how changes in network parameters affect the loss. It applies the chain rule of calculus to efficiently compute gradients through connected operations. These gradients indicate directions in which parameters can change to influence the training objective.
After a forward pass and loss calculation, backpropagation works backward through the computational graph. It calculates gradients for the relevant trainable parameters. An optimization algorithm then uses those gradients to determine how the parameters should be updated during the training step.
Backpropagation is a central part of training many modern neural networks. However, calculating gradients alone does not guarantee that a model will learn useful patterns. Architecture, initialization, learning rates, data quality, and optimization choices also influence the final training results.
What Is Gradient Descent in Deep Learning?
Gradient descent is an optimization approach used to reduce a model’s loss by adjusting trainable parameters. It relies on gradients that describe how the loss changes with respect to those parameters. The optimizer uses this information to choose updates that aim to improve the training objective.
The learning rate controls the size of many parameter updates during optimization. An excessively large learning rate may produce unstable training, while a very small one can slow progress. Appropriate settings depend on the model, dataset, optimizer, and overall training conditions.
Modern deep learning often uses optimization methods such as stochastic gradient descent and Adam. These methods provide different strategies for updating parameters using gradient information. Selecting an optimizer involves balancing training stability, computational efficiency, and performance on the intended learning task.
How Deep Learning Models Make Predictions
Once a deep learning model has been trained, it can process new information through a stage called inference. During inference, the network uses its learned parameters to calculate outputs. It does not normally update those parameters unless an additional learning process is specifically enabled.
For example, a trained image classifier can receive a photograph and produce category scores. A language model can process a prompt and generate a sequence of tokens. Both systems apply previously learned relationships, although their architectures and output processes differ significantly.
Prediction quality depends on how well the new information matches the conditions represented during development. Unfamiliar inputs, noisy data, or changing environments can reduce reliability. Real-world applications often require monitoring and periodic evaluation to maintain acceptable performance.
Different Types of Deep Learning Models
Deep learning includes several architectures designed to process different forms of information. Convolutional neural networks are commonly associated with visual tasks, while recurrent networks were developed for sequential data. Transformers and autoencoders provide additional approaches for learning useful data representations.
Convolutional neural networks use filters to identify local patterns and relationships within structured inputs. Recurrent neural networks maintain information across sequence steps, although their effectiveness depends on the design. Transformers use attention mechanisms to model relationships between elements and have become especially important in language processing.
Autoencoders learn to represent data through encoding and reconstruction tasks. Generative neural networks can also learn patterns that support the creation of new content. Choosing an architecture depends on the task, available data, computational resources, and the level of performance required.
How Deep Learning Recognizes Images
Deep learning models can recognize images by learning visual patterns from training examples. In a conventional convolutional network, filters process local image regions to extract useful features. Later operations combine those features into representations suitable for classification, detection, or other visual tasks.
Consider a model trained to identify different types of vehicles. It may learn patterns associated with wheels, windows, overall shapes, and surrounding visual details. These features contribute to predictions, although the model does not necessarily understand objects in the same way humans do.
Modern computer vision also uses transformer-based architectures and other specialized neural networks. These systems support applications such as image segmentation, manufacturing inspection, and medical image analysis. Reliable results require diverse training examples and testing across realistic lighting, camera, and environmental conditions.
How Deep Learning Understands Human Language
Deep learning supports natural language processing by learning statistical relationships within large collections of text. Language models convert words or text fragments into numerical token representations. Neural networks then process these representations to predict, classify, transform, or generate language according to their objectives.
Modern language models frequently use transformer architectures with attention mechanisms. These mechanisms help represent relationships between tokens in a sequence. Through extensive training, models can develop capabilities useful for translation, summarization, question answering, and conversational applications.
Despite producing fluent responses, language models do not guarantee factual accuracy or reliable reasoning in every situation. They may generate incorrect details or misunderstand context. Human review, appropriate evaluation, and additional verification remain important when using generated information for consequential tasks.
Real-World Applications of Deep Learning
Deep learning is used across industries to process complex information and support automated tasks. Healthcare researchers apply it to medical imaging, while financial organizations investigate its use in fraud detection. Businesses also use neural networks for selected recommendation, forecasting, and document-processing applications.
In everyday technology, deep learning can support speech assistants, automatic captions, image editing, and translation services. Some navigation and transportation systems also use learned models to interpret sensor information. These applications often combine deep learning with conventional programming and other analytical methods.
The value of deep learning depends on whether it solves a meaningful problem reliably. Not every task requires a complex neural network, and simpler techniques may sometimes perform equally well. Organizations should evaluate performance, cost, privacy requirements, and operational risks before deployment.
Benefits of Deep Learning Technology
Deep learning can identify complex patterns in images, language, sound, and numerical information. Its layered representations help models learn relationships that would be difficult to describe through fixed programming rules. This capability makes neural networks useful across a wide range of challenging computational tasks.
Another benefit is the ability to learn useful features directly from suitable training data. Traditional machine learning approaches sometimes require more manual feature engineering. Deep learning can reduce that effort in certain applications, particularly when processing complex information such as photographs or speech recordings.
Pretrained models and transfer learning provide additional practical advantages. Developers can adapt existing networks to related tasks rather than building every model entirely from scratch. This approach may reduce training costs and data requirements, although results still depend on compatibility and evaluation.
Challenges and Limitations of Deep Learning
Deep learning systems can require substantial computing power, especially when models contain many parameters. Training may involve specialized processors, large datasets, and extensive experimentation. These requirements can increase development expenses, infrastructure demands, and energy consumption compared with simpler approaches.
Data quality creates another major limitation because models learn from the examples available during training. Incomplete or biased datasets may cause unreliable predictions across different situations. Networks can also overfit training data, meaning they perform well on familiar examples but struggle with new information.
Complex models may be difficult to interpret, test, and maintain. Their outputs can be affected by unexpected inputs, changing data patterns, or adversarial manipulation. Responsible deployment requires performance monitoring, security measures, and appropriate human oversight rather than assuming that a trained model is always correct.
How Beginners Can Start Learning Deep Learning
Beginners should first understand basic machine learning ideas such as datasets, features, training, and evaluation. Learning fundamental Python programming is also helpful because many deep learning tools support it. Basic knowledge of algebra, probability, and calculus can make more advanced explanations easier to understand.
Next, explore simple neural networks through small practical projects. Handwritten digit recognition and basic image classification are common starting points. These projects help demonstrate how input data, predictions, loss functions, backpropagation, and optimization work together during training.
Frameworks such as PyTorch and TensorFlow provide tools for creating and experimenting with neural networks. Start with small datasets and understandable architectures before attempting large language models or complex applications. Developing strong evaluation habits is just as important as learning how to train a network.
Conclusion
Deep learning works by processing data through multiple layers of artificial neural networks. These networks use trainable parameters, mathematical operations, and optimization methods to learn useful patterns. Forward propagation generates predictions, while loss calculations and backpropagation help guide improvements during training.
The technology supports important applications in image recognition, language processing, healthcare research, finance, and everyday digital services. Its ability to learn complex representations makes it valuable for tasks that are difficult to solve using fixed rules. However, successful results depend on quality data, appropriate architecture, and reliable evaluation.
Understanding how deep learning works begins with a few central ideas rather than complicated mathematical formulas. Learning about neural networks, training cycles, gradients, and inference provides a strong foundation. With practical experimentation and continued study, these concepts become easier to apply to real-world problems.
Frequently Asked Questions
How does deep learning work in simple words?
Deep learning works by passing data through layers of artificial neural networks. During training, the network adjusts its internal parameters to learn patterns, allowing it to make predictions about new information.
What are the main steps in deep learning?
The main steps include preparing data, building a neural network, generating predictions, calculating loss, and updating parameters. Training repeats these steps before the model is evaluated and used for inference.
What is an example of how deep learning works?
An image recognition model learns from labeled photographs of different objects. After training, it processes unfamiliar images and predicts their categories using visual patterns learned from the training examples.
What is the difference between machine learning and deep learning?
Machine learning includes various algorithms that learn patterns from data. Deep learning is a specialized branch that uses multilayer neural networks, often making it suitable for complex image, audio, and language tasks.
Does deep learning need a lot of data?
Deep learning often benefits from large, representative datasets, especially when training complex networks from scratch. However, pretrained models and transfer learning can reduce the amount of new training data required for certain tasks.