
Machine learning is one of the most important technologies shaping the modern digital world. From personalized recommendations on streaming platforms to fraud detection in banking, machine learning helps computers recognize patterns, analyze information, and make predictions. It is widely used in artificial intelligence, healthcare, education, business, and many other industries.
Understanding what machine learning is can help beginners explore how intelligent computer systems work. Although the technology may sound complicated, its basic idea is straightforward. This guide explains how machine learning works, its main types, popular algorithms, real-world applications, benefits, challenges, and future possibilities.
What Is Machine Learning?
Machine learning is a branch of artificial intelligence that enables computer systems to learn patterns from data and use those patterns to make predictions or decisions. Instead of relying entirely on explicitly written instructions, machine learning algorithms improve their performance through training. This approach allows computers to handle tasks involving complex information. Examples include recognizing images, filtering unwanted emails, and predicting customer behavior.
Traditional software usually follows rules programmed by developers to complete specific tasks. Machine learning systems, however, identify relationships within training data and develop mathematical models. These models can then process new information and produce results based on learned patterns. The approach is particularly useful when creating detailed rules manually would be difficult or inefficient.
Machine learning does not mean computers understand information exactly as humans do. Most models identify statistical relationships rather than develop human-like reasoning. Their accuracy depends on data quality, training methods, and the conditions in which they operate. Understanding these limitations is important when evaluating machine learning applications and their reliability.
How Does Machine Learning Work?
Machine learning works by analyzing data to identify patterns that can support predictions or automated decisions. The process usually begins with collecting information relevant to a particular problem. Developers prepare this information and select an appropriate learning algorithm. The algorithm then uses training data to create a model that can perform the intended task.
During training, the model adjusts internal parameters to improve its results according to a defined objective. For example, an email classification model may learn differences between unwanted messages and legitimate emails. It examines examples and identifies features associated with each category. Repeated training helps the system improve its performance on similar tasks.
After training, developers evaluate the model using data that was not used to fit its parameters. This process helps determine whether it can handle unfamiliar examples rather than simply memorize training information. Once the results meet appropriate requirements, the model may be deployed into an application. Its performance should continue to be monitored because real-world conditions can change.
Main Steps in the Machine Learning Process
The first step in a machine learning project is defining a clear problem and collecting relevant data. This information might include customer transactions, product images, website activity, or sensor measurements. Developers must evaluate whether the data represents the situations the model will encounter. Poor-quality or unrepresentative information can weaken the final results.
Next comes data preparation, which may involve removing duplicates, addressing missing values, and converting information into usable formats. The dataset is commonly divided into training, validation, and testing portions. Developers then select an appropriate algorithm and train the model using the prepared information. Validation results help guide adjustments to improve performance.
The final stages involve testing, deployment, and ongoing monitoring. Testing measures performance on previously unseen data and helps identify potential weaknesses. Deployment allows the trained model to generate predictions within an application or business workflow. Regular monitoring is necessary because changing data patterns can gradually reduce accuracy and reliability.
Types of Machine Learning
Machine learning is commonly divided into several categories based on how algorithms learn from information. The main types include supervised learning, unsupervised learning, and reinforcement learning. Each approach solves different problems and requires different forms of training experience. Additional methods, including self-supervised and semi-supervised learning, are also important in modern applications.
Supervised learning uses examples with known answers, while unsupervised learning searches for patterns without predefined labels. Reinforcement learning involves learning through interactions with an environment and receiving feedback in the form of rewards. These approaches can sometimes be combined within larger artificial intelligence systems. The appropriate choice depends on the task and available information.
Understanding machine learning types makes it easier to recognize why different algorithms behave differently. A system predicting house prices requires a different training approach from one grouping customers into categories. Similarly, a robot learning movement strategies may require interactive training. Selecting the correct learning method is fundamental to developing an effective model.
Supervised Machine Learning Explained
Supervised learning is a machine learning approach that trains models using labeled examples. Each training example contains input information and a corresponding expected output. The algorithm learns relationships between these inputs and outputs to make predictions about unfamiliar data. This method is widely used for classification and regression problems.
Classification involves assigning information to predefined categories. For example, an email filter may classify incoming messages as spam or legitimate communication. Regression involves predicting continuous numerical values, such as property prices or future energy consumption. Both tasks rely on examples that help the model learn useful relationships.
Supervised learning is valuable when reliable labeled datasets are available. However, collecting and labeling large amounts of information can require significant time and resources. Models may also perform poorly when training data contains errors or does not represent real-world conditions. Careful evaluation is necessary before using their predictions for important decisions.
Unsupervised Machine Learning Explained
Unsupervised learning focuses on discovering patterns in datasets that do not contain predefined target labels. Instead of learning from known answers, the algorithm examines similarities, differences, and underlying structures. This approach can reveal relationships that may not be obvious through manual analysis. It is especially useful when large quantities of unlabeled information are available.
Clustering is one common unsupervised learning technique used to group similar observations. Businesses may use clustering to identify customers with comparable purchasing patterns or interests. Another technique, dimensionality reduction, simplifies complex datasets while preserving useful information. These methods support exploratory analysis and can assist with other machine learning tasks.
Unsupervised learning has limitations because discovered patterns do not necessarily represent meaningful real-world categories. Results often require interpretation and additional validation before they can support business decisions. Different algorithms may also produce different groupings from the same data. Domain knowledge is important for determining whether the identified patterns are genuinely useful.
Reinforcement Learning Explained
Reinforcement learning is a machine learning approach in which an agent learns by interacting with an environment. The agent takes actions, observes outcomes, and receives rewards or penalties based on a defined objective. Over time, it develops strategies intended to maximize its cumulative rewards. This method is useful for problems involving sequences of decisions.
A common example involves training a computer program to play a game. The agent explores different actions and learns which strategies improve its chances of success. Reinforcement learning can also support robotics, resource allocation, and certain optimization problems. However, these applications often require carefully designed training environments and reward systems.
One major challenge involves balancing exploration with the use of previously successful strategies. The agent must sometimes try unfamiliar actions to discover potentially better results. Training can also require substantial computational resources and many interactions. Poorly designed rewards may encourage undesirable behavior, making careful system design essential.
What Is Deep Learning in Machine Learning?
Deep learning is a specialized area of machine learning that uses neural networks containing multiple processing layers. These networks learn representations of information through mathematical transformations. Deep learning is particularly useful for complex data such as images, audio, and natural language. Many modern artificial intelligence applications rely on deep learning techniques.
Artificial neural networks consist of interconnected computational units organized into layers. During training, the network adjusts numerical weights to reduce prediction errors or improve another learning objective. Different architectures are designed for different tasks and data structures. Convolutional networks, transformers, and other neural network designs are used across various applications.
Deep learning models can achieve impressive results, but they often require substantial data and computational power. Their internal behavior may also be difficult to interpret, particularly in very large networks. Training costs, energy consumption, and reliability are important considerations. Traditional machine learning methods can still be preferable for smaller or simpler datasets.
Machine Learning vs Artificial Intelligence
Artificial intelligence is the broader field concerned with developing systems capable of performing tasks associated with intelligent behavior. Machine learning is one important approach used within that field. AI systems may also rely on manually programmed rules, search algorithms, or other techniques. Therefore, not every artificial intelligence system necessarily uses machine learning.
Machine learning specifically focuses on developing models that learn patterns from data. Artificial intelligence includes a wider range of technologies, such as planning systems, knowledge representation, and automated reasoning. Many modern AI applications combine machine learning with additional software components. Understanding this relationship helps clarify why the terms are related but not identical.
For example, a traditional rule-based chatbot may respond using predefined conversation patterns without learning from data. A machine learning chatbot can use trained models to classify requests or generate responses. Both may fall under the broader category of artificial intelligence. Their capabilities and limitations depend on the technologies used in their development.
Common Machine Learning Algorithms
Machine learning algorithms are mathematical procedures used to identify patterns and build predictive models. Popular examples include linear regression, logistic regression, decision trees, random forests, and support vector machines. Each algorithm has particular strengths and limitations. Choosing the appropriate method depends on the dataset, objective, and performance requirements.
Linear regression is commonly used to predict numerical values based on relationships between variables. Decision trees create prediction rules by splitting data according to different features. Random forests combine predictions from multiple decision trees to improve robustness in many situations. These algorithms are frequently introduced in beginner machine learning courses because their underlying principles are relatively accessible.
Other important techniques include k-means clustering, gradient boosting, and neural networks. K-means groups similar observations, while gradient boosting builds predictive models by combining multiple weaker learners. Neural networks can model complex relationships across diverse data types. Developers compare algorithms through appropriate testing rather than assuming one method always performs best.
Real-World Machine Learning Examples
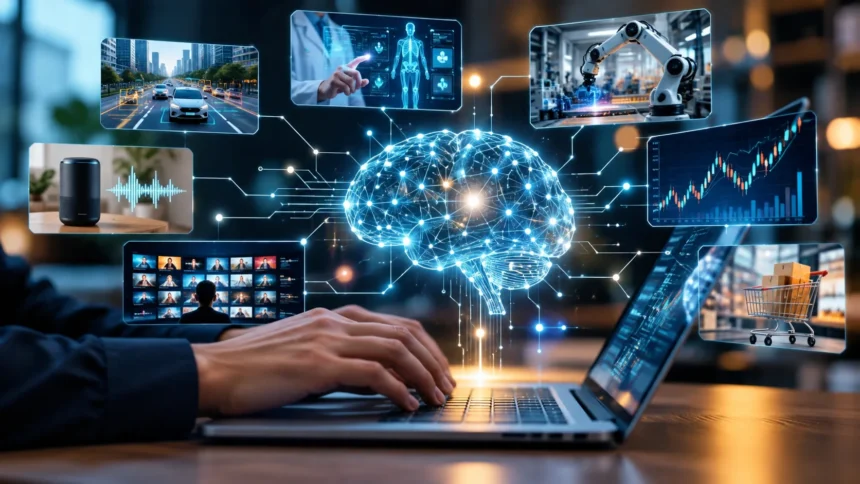
Machine learning appears in many digital services that people use every day. Streaming platforms analyze viewing patterns to recommend movies, shows, and other content. Email services use classification models to identify unwanted messages. Online shopping platforms may also use predictive systems to suggest products based on customer activity.
Smartphones provide additional examples through speech recognition, predictive typing, and photo organization. Machine learning can help identify spoken words, suggest likely text, and recognize objects within images. Navigation applications may use predictive models to estimate travel conditions. These features demonstrate how trained systems can support everyday activities without requiring users to understand the underlying algorithms.
Financial institutions also use machine learning to identify unusual transaction patterns that may indicate fraud. Manufacturers apply predictive models to equipment data to anticipate maintenance needs. Agricultural organizations may analyze satellite imagery to monitor crop conditions. These examples show how machine learning can support decision-making across industries with very different requirements.
Machine Learning Use Cases in Healthcare
Healthcare organizations use machine learning for selected tasks involving medical images, administrative information, and clinical data analysis. Some systems assist trained professionals in identifying patterns within scans or laboratory results. Others support appointment scheduling, resource planning, or research activities. These technologies are intended to improve particular workflows rather than replace professional medical judgment.
Machine learning can also help researchers analyze large datasets related to diseases and treatment outcomes. By examining complex relationships, models may identify patterns that deserve further investigation. However, statistical associations do not automatically demonstrate medical causation. Clinical validation and careful interpretation remain necessary before research findings can influence patient care.
Healthcare applications face significant challenges involving privacy, accuracy, fairness, and patient safety. A model trained on limited populations may not perform equally well for everyone. Incorrect predictions can have serious consequences when used in clinical settings. Strong evaluation, professional oversight, and appropriate regulatory compliance are therefore essential for responsible implementation.
Machine Learning in Business and Marketing
Businesses use machine learning to analyze customer behavior, estimate demand, and improve operational decisions. Predictive models can identify patterns in historical sales, website activity, and purchasing behavior. These insights may support inventory management and business planning. However, predictions remain uncertain and should be evaluated alongside current market conditions.
Digital marketing provides numerous machine learning applications, including audience segmentation and campaign performance analysis. Models may estimate the likelihood of customer conversions or help personalize product recommendations. Search engines and advertising platforms also use machine learning in various ranking and delivery systems. These applications can improve relevance when supported by suitable data and effective controls.
Customer service teams may use machine learning to categorize support requests and identify recurring problems. Businesses can also analyze customer feedback to understand common concerns and satisfaction trends. These tools help process information that would otherwise require extensive manual review. Responsible implementation should consider accuracy, customer privacy, and the possibility of biased predictions.
Machine Learning in Education
Machine learning is increasingly used in educational technology to support personalized learning experiences. Certain systems analyze student performance and recommend practice activities based on identified learning needs. Teachers may use educational analytics to recognize areas where additional instruction could help. These tools can support classroom planning when interpreted responsibly.
Automated assessment systems may assist with checking structured answers or identifying patterns in submitted work. Language learning applications can use speech recognition to provide feedback on pronunciation. Recommendation systems may suggest lessons based on previous activity. However, automated feedback can be incorrect and should not replace meaningful guidance from educators.
Privacy and fairness are important considerations when machine learning systems process student information. Educational models may reflect limitations or biases present in their training datasets. Students also benefit from understanding how automated recommendations are generated and used. Human oversight helps ensure that technology supports learning rather than determining educational opportunities unfairly.
Benefits of Machine Learning
One major benefit of machine learning is its ability to process large amounts of information efficiently. Models can identify patterns across datasets that would be difficult to examine manually. This capability supports prediction, classification, and automated analysis in many industries. When properly developed, machine learning systems can help organizations make more informed decisions.
Machine learning also enables certain applications to adapt as new information becomes available. Models can be retrained or updated to reflect changing customer behavior, environmental conditions, or operational needs. This adaptability is useful in situations where manually maintained rules would become outdated. However, updates require monitoring and evaluation to avoid introducing new errors.
Another advantage is the ability to personalize digital experiences based on relevant data. Recommendation systems, language tools, and accessibility technologies can respond to different user needs. These applications may improve convenience and efficiency when designed responsibly. Their benefits depend on maintaining accuracy, protecting privacy, and considering how automated decisions affect people.
Challenges and Limitations of Machine Learning
Data quality is one of the biggest challenges in machine learning development. Incomplete, inaccurate, or biased datasets can produce unreliable predictions. Even technically sophisticated algorithms may struggle when their training information does not represent real-world conditions. Careful data preparation and evaluation are therefore fundamental to successful projects.
Another challenge involves overfitting, which occurs when a model learns training data too closely and performs poorly on unfamiliar examples. Underfitting occurs when a model is too limited to capture important relationships. Developers use validation methods and appropriate model design to manage these problems. Achieving reliable generalization is more important than simply obtaining excellent training accuracy.
Machine learning systems may also raise concerns about explainability, privacy, security, and computational costs. Some advanced models are difficult to interpret, making their decisions challenging to explain. Training and operating large systems can require substantial computing resources. Organizations must consider these limitations before relying on automated predictions in sensitive or high-impact situations.
How to Start Learning Machine Learning
Beginners can start learning machine learning by developing a basic understanding of mathematics, statistics, and programming. Topics such as probability, algebra, and data analysis provide useful foundations. Python is a popular programming language because of its accessible syntax and extensive machine learning libraries. Learning these fundamentals makes more advanced concepts easier to understand.
After building basic programming skills, beginners can explore libraries such as NumPy, pandas, and scikit-learn. These tools support data preparation, statistical analysis, and introductory machine learning models. Simple projects involving classification or numerical prediction provide practical experience. Working with manageable datasets helps learners understand each stage of model development.
Practical experience is especially valuable when learning how algorithms behave outside textbook examples. Beginners can experiment with decision trees, linear regression, and clustering methods using publicly available educational datasets. Evaluating model accuracy and understanding errors are important parts of this process. Gradually progressing toward neural networks and deep learning can build confidence without unnecessary complexity.
The Future of Machine Learning
Machine learning continues to develop as researchers improve algorithms, computing systems, and training techniques. Advances in foundation models and deep learning have expanded capabilities in language processing, image generation, and multimodal analysis. Researchers are also exploring methods that require less labeled data. These developments may make machine learning useful across an even wider range of applications.
Another important direction involves making machine learning systems more efficient and reliable. Smaller models and specialized hardware can help reduce certain computational requirements. Research into model evaluation, interpretability, and robustness aims to improve performance under changing conditions. These improvements may support broader adoption without depending exclusively on increasingly large models.
The future of machine learning will also depend on responsible development and appropriate governance. Privacy protection, transparent evaluation, and human oversight are important for systems influencing significant decisions. Organizations will need to balance innovation with practical limitations and social responsibilities. Machine learning is likely to remain an important technology, but its value will depend on how carefully it is applied.
Conclusion
Machine learning is a powerful branch of artificial intelligence that allows computers to identify patterns and make predictions using data. Its main approaches include supervised learning, unsupervised learning, and reinforcement learning. Deep learning provides additional capabilities through multilayer neural networks. Together, these techniques support applications ranging from personalized recommendations to scientific research.
Understanding how machine learning works involves learning about data preparation, model training, evaluation, and deployment. Each stage contributes to the accuracy and usefulness of a system. Although machine learning offers significant benefits, challenges such as biased data, limited explainability, and changing conditions require careful attention. Reliable results depend on thoughtful development and ongoing monitoring.
For beginners, machine learning offers an opportunity to explore programming, statistics, artificial intelligence, and practical problem-solving. Starting with basic algorithms and simple projects provides a strong foundation for further learning. As the technology continues to evolve, understanding its capabilities and limitations will become increasingly valuable across many industries.
Frequently Asked Questions
What is machine learning in simple words?
Machine learning is a technology that helps computers learn patterns from data and use those patterns to make predictions or decisions. It allows software to perform certain tasks without manually programming every rule.
What are the three main types of machine learning?
The three main types are supervised learning, unsupervised learning, and reinforcement learning. Supervised learning uses labeled examples, unsupervised learning identifies hidden patterns, and reinforcement learning improves strategies through feedback from actions.
What is an example of machine learning?
An email spam filter is a common example of machine learning. It analyzes patterns in messages to classify new emails as spam or legitimate, helping users manage their inboxes.
Is machine learning the same as artificial intelligence?
No, machine learning is a branch of artificial intelligence. AI is the broader field of intelligent computer systems, while machine learning specifically focuses on learning patterns from data.
Is Python necessary to learn machine learning?
Python is not strictly required, but it is widely recommended for beginners because of its readable syntax and useful libraries. Other programming languages can also support machine learning development.